Tutorial · Research edition
Podcast Loudness and Export Settings: A Delivery Workflow
Prepare podcast audio with measured loudness, true-peak headroom, appropriate codec settings, metadata checks, and a decoded-file quality-control pass.
A podcast master can be clean in the editor and still fail after encoding. Loudness, true peak, channel count, sample rate, bit rate, metadata, and the host's own processing interact at the delivery boundary.
The responsible workflow keeps a high-quality master, creates a destination file from current requirements, measures before encoding, and listens to the decoded upload candidate—not only the timeline.
Original synthetic demonstration
Compare peak and integrated loudness
Turn playback volume down first. These eight-second test tones peak at −12 dBFS, including a steady 1 kHz tone. Listening is optional; use the descriptions and measured values instead.
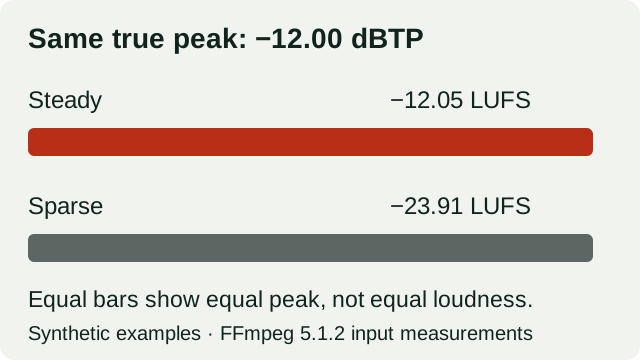
Both synthetic files measure −12.00 dBTP, while their integrated loudness differs: steady −12.05 LUFS, sparse −23.91 LUFS. Equal peak does not mean equal loudness.
Download the two WAV files to repeat the measurements with an integrated-loudness and true-peak meter. Listening is optional; the measured values above provide the comparison.
Steady synthetic tone
8 seconds. Stereo 1 kHz tone. Measured input: −12.05 LUFS integrated, −12.00 dBTP.
Download loudness-steady.wav · WAV (48 kHz, 16-bit PCM) · 8 seconds · 1,536,044 bytes
File integrity
SHA-256: 70e73e2e2a9706479006786f326e229403076d377893b45017b925dc6c95cb22
Sparse synthetic tone
8 seconds. Stereo 1 kHz bursts over a quieter bed. Measured input: −23.91 LUFS integrated, −12.00 dBTP.
Download loudness-peaky.wav · WAV (48 kHz, 16-bit PCM) · 8 seconds · 1,536,044 bytes
File integrity
SHA-256: a32a1c0b8cb3de4ad7c14348e474d087efbadbd7541c22fee3ad7adb7bac85ca
Generated and measured by StudioSignalLab on October 29, 2026. Shipped files are pinned by hash. Measurements can be repeated; different encoders, fonts or builds may produce different bytes. These examples contain no speech, music or hardware capture.
Separate mix decisions from delivery targets
Editing, EQ, dynamics, restoration, music balance, and fades create the master. Loudness normalization and peak control prepare that master for a distribution target. Pushing every phrase toward the target with heavy compression can reduce intelligibility and introduce distortion.
Measure the complete program, including intro, ads, music, and credits. A short loud segment does not describe integrated loudness; a safe sample peak does not guarantee safe true peak after encoding.
A documented target—not a universal law
Apple recommends preconditioning podcast audio to around -16 dB LKFS with ±1 dB tolerance and a true peak not exceeding -1 dBFS, using ITU-R BS.1770-5 calculations. Apple says this should occur before encoding because lossy compression may clip when true-peak headroom is insufficient.
Treat that as a current, traceable destination target. If a host, broadcaster, advertiser, or client supplies another specification, create and label the appropriate deliverable rather than forcing one file into every use.
Format and channel decisions
For RSS audio, Apple currently accepts MP3 or AAC and recommends AAC in MP4 for efficient streaming and accurate seeking. At 44.1 or 48 kHz, its recommended ranges are 64–128 kbps mono and 128–256 kbps stereo for both AAC and MP3.
Mono is efficient for a centered speech-only program. Stereo is required when music, spatial ambience, or deliberate left/right production carries meaning. Do not convert a mono voice into two channels and call it richer; choose based on content and compatibility.
Export ladder
Create files in a deliberate order.
- Archive master: lossless, full project sample rate/bit depth, no distribution codec.
- Delivery master: correct program edits, measured loudness and true peak, clean beginning/end.
- Encoded RSS file: host-supported MP3 or AAC, intentional channel count and bit rate.
- Platform video audio: aligned with the video workflow and platform requirements.
- Transcript, chapters, artwork, title, explicit flag, and episode metadata checked against the same version.
Decoded-file QC
Open the encoded file in a new session or player. Confirm duration, channel layout, start/end, ID3 or container metadata, chapter behavior when used, and absence of codec artifacts around sibilants, music, applause, and noise-reduced speech.
Measure again after encoding and compare against the master at matched playback level. Upload privately or as a draft when the platform permits, then inspect what listeners will actually receive.
Release record
Store the filename, checksum, duration, integrated loudness, loudness range when relevant, maximum true peak, sample rate, channel count, codec, bit rate, export preset version, and reviewer. This record makes a later correction reproducible rather than forensic.
Same peak, different loudness: our measured example
The two eight-second synthetic WAV files below have the same 1 kHz tone and the same sample peak of −12.00 dBFS. One is steady; the other uses brief full-level bursts over a quieter bed. FFmpeg 5.1.2 measured their input integrated loudness as −12.05 and −23.91 LUFS, while both measured −12.00 dBTP. The approximately 11.86 LU difference comes from these particular signals; it is not a prediction for speech.
Start with playback volume down: these are audible test tones, including an eight-second steady tone. Listening is optional. The measured values and text descriptions provide the lesson without playback. Neither file is a podcast, an equipment recording or an encoder listening test.
We measured the delivered input files using FFmpeg loudnorm with I=−16, TP=−1, LRA=11 and print_format=json; only the input statistics are reported here. A second pass using its ebur128 filter gave −12.0 and −23.7 LUFS and −12.0 dBFS true peak after rounding. The sparse signal differs by about 0.21 LU between filters; we retain the loudnorm input value for the arithmetic rather than claiming identical meters. These are two filters in the same FFmpeg build, not independent measurement products. The processed output of loudnorm was discarded.
Work the gain and headroom before processing
For an illustrative target of −16 LUFS, linear gain is target minus measured loudness. The steady file needs −16 − (−12.05) = −3.95 dB. Its predicted true peak becomes −15.95 dBTP. The sparse file needs −16 − (−23.91) = +7.91 dB, with a predicted true peak of −4.09 dBTP. Both arithmetic results leave room below an illustrative −1 dBTP ceiling. They are predictions for linear gain, not measurements of a limiter or of the discarded loudnorm output.
Now take an invented file at −23.9 LUFS with a −2 dBTP true peak. Reaching −16 LUFS would need +7.9 dB, but the headroom to a −1 dBTP ceiling is only +1 dB. Gain alone cannot satisfy both constraints. The requested gain would predict +5.9 dBTP, above the ceiling. Revisit the mix or use deliberate dynamic processing, then measure again; do not assume a louder export has passed.
Write down four values before changing anything: measured integrated loudness, measured true peak, the actual destination target and its ceiling. Calculate the required gain and the resulting peak. Keep these predictions separate from the measured delivery file, and inspect the encoded result as described above. Apple’s documented destination guidance remains one scoped example, not a universal specification.
Sources and verification
Claims were checked against the following first-party documentation on October 29, 2026. Product capabilities can change; verify current documentation before buying or changing a production system.
Frequently asked questions
What loudness should a podcast target?
Apple currently recommends about -16 dB LKFS with ±1 dB tolerance and true peak no higher than -1 dBFS. Treat this as a documented destination recommendation and follow any different host or client specification.
Should a spoken-word podcast be mono or stereo?
Mono is efficient when all meaningful content is centered speech. Use stereo when music, ambience, or intentional spatial production needs separate left and right channels.
Why check the encoded file?
Lossy encoding and metadata writing can introduce clipping, artifacts, channel mistakes, or version mismatches that are not audible in the lossless editing timeline.